If you are building a recruiting product, an ATS, a talent marketplace or an internal sourcing tool, you hit the same wall early: your users want to find people who are not already in your database.
An applicant tracking system knows about applicants. A job board knows about people who applied. Neither helps a recruiter who needs to find the forty people in a market who match a brief and have never heard of the role.
A candidate sourcing API fills that gap. You send criteria, you get back professional records matching them, and the matching happens against a set far larger than anything you maintain yourself.
This covers what to look for in one, which filters actually narrow a candidate search, the sourcing motions worth supporting, how to turn a match into someone a recruiter can contact, and the parts that break once real users are on it.
What a sourcing API is, and what it is not
Worth separating four things that get conflated in this category.
Sourcing finds people matching criteria when you do not know who they are. Criteria in, many out.
Enrichment takes a candidate you already have and fills in what you do not know. One identifier in, one complete record out.
Verification confirms a specific attribute is currently true, most often whether an email address can receive mail.
ATS integration reads and writes your customer's existing applicant data. A different problem entirely, usually solved by a unified API layer, and not what this post is about.
Most recruiting products need the first three. They are separate operations with separate pricing, and buying a tool that only does enrichment when your users want sourcing is a common and expensive mistake.
The four sourcing motions
Recruiters search in four distinct ways, and a product that only supports the first will feel thin to anyone experienced.
Criteria search. A brief exists: a role, a location, a skill set, a seniority band. Find people matching it. This is the obvious one and the one everyone builds.
Lookalike expansion. A recruiter has one person who fits perfectly, often a previous placement or a current employee. Find more like them. This is how experienced recruiters actually work, and it is better than criteria search because articulating why someone fits is harder than pointing at them.
Alumni sourcing. Find people who studied somewhere, or who used to work somewhere. Strong for graduate hiring, for sector-specific experience, and for competitor talent.
Trigger sourcing. Find people whose circumstances just changed. Someone who recently left a company is in a short window of unusual receptiveness.
Each needs different endpoints. A product supporting all four is meaningfully more useful than one supporting criteria search alone.
Criteria search: the filters that matter
Almost every provider offers title, company and location. Those three produce thousands of results, which is a market rather than a shortlist. The filters below are where a usable candidate search comes from.
Role, scoped to the present
1from renidly import Renidly
2
3renidly = Renidly()  # reads RENIDLY_API_KEY from the environment
4
5page = renidly.data.people.search(
6    title="platform engineer",
7    current_only=True,
8    geo_country_code="US",
9    limit=50,
10)
If your stack is Node, the same call. Note that SDK method names follow the language convention while Data API filter parameters keep their snake_case names in both languages:
1import { Renidly } from "renidly";
2
3const renidly = new Renidly();
4
5const page = await renidly.data.people.search({
6  title: "platform engineer",
7  current_only: true,
8  geo_country_code: "US",
9  limit: 50,
10});
current_only is the parameter that decides whether your results make sense. Without it, a title search matches anyone who ever held that title, so someone who was a platform engineer in 2016 and is now a VP comes back in a platform engineer search. For sourcing, that is occasionally what you want and usually not.
Keep the title string broader than feels comfortable. Job titles are not a controlled vocabulary, and "Platform Engineer", "Infrastructure Engineer" and "Site Reliability Engineer" are frequently the same brief. Matching is partial with a three-character minimum, so go wide on the string and narrow with structured filters.
Capability, properly
Skills filtering uses normalized names rather than free text, which means there is a discovery step before you can filter:
1matches = renidly.data.skills.search("kubernetes")
2for s in matches:
3    print(s.id, s.name, s.normalized_name)
Then feed the normalized names in. The parameter that matters is skills_match, which defaults to any:
1shortlist = renidly.data.people.search(
2    title="engineer",
3    current_only=True,
4    skills="kubernetes,terraform,go",
5    skills_match="all",          # AND, not OR
6    skill_count_min=8,
7)1const shortlist = await renidly.data.people.search({
2 title: "engineer",
3 current_only: true,
4 skills: "kubernetes,terraform,go",
5 skills_match: "all",
6 skill_count_min: 8,
7});Leaving skills_match on its default is the single most common cause of a candidate search returning far more people than expected. The default is a union: someone listing only Go matches a Kubernetes-Terraform-Go filter. For a shortlist you almost always want all.
skill_count_min is a different kind of signal. It is a proxy for profile completeness rather than for competence, and a floor of five to ten quietly removes stub profiles without you having to reason about which specific skills matter.
For regulated or credential-heavy hiring, certifications and certification_authority are stronger than skills, because a credential is verifiable and a self-reported skill is not. If you source into security, cloud, accounting, healthcare or anything licensed, filter on the credential.
Cache the discovery lookups. Skill identifiers and normalized names are stable, and you should not be resolving "kubernetes" to its normalized form on every search your users run.
Education
Three filters work directly: education_level (phd, master, bachelor, associate), degree as free text, and field_of_study as free text.
Institution filtering needs a discovery step, because it takes opaque identifiers rather than names:
1schools = renidly.data.institutions.search("stanford university")
2inst_id = schools[0].id        # inst_…
3
4candidates = renidly.data.people.search(
5    institution_ids=inst_id,
6    title="product manager",
7    current_only=True,
8    field_of_study="computer science",
9)
Up to twenty institution identifiers can be combined, which makes "alumni of any of these ten schools, currently in this role" a single query.
Career stage
This group is where candidate search stops being a demographic filter and starts predicting whether someone will take your call.
| Filter | What it isolates |
|---|---|
tenure_min_years | Deeply embedded, harder to move, more senior |
tenure_max_years | Recently started, unlikely to move again soon |
last_change_within_days + last_change_type | Who moved, and in which direction |
company_count_min / company_count_max | Career mobility |
current_company_count_min | Fractional, advisory, portfolio careers |
is_boomerang | Returned to a former employer |
The combination that matters most for sourcing:
1movable = renidly.data.people.search(
2    title="data engineer",
3    current_only=True,
4    tenure_min_years=2,
5    tenure_max_years=5,
6    geo_country_code="GB",
7)
Someone two to five years into a role is in the band where they have real experience to show and have usually stopped being new. Under a year, they just moved and are unlikely to move again. Past six or seven years, they are embedded, and the conversation is different.
company_count_max with a low value finds people who have stayed put, which can mean deep institutional knowledge or a long approval cycle. company_count_min with a high value finds people who move often, adopt quickly and are easier to reach but harder to retain. Both are useful for opposite briefs.
is_boomerang is rare as a first-class filter and genuinely interesting. Someone who left a company and returned is a loyalty signal, and for employer-brand work it identifies people who can speak to why.
Availability
Every profile record carries flags, including is_open_to_work. It costs nothing extra because it arrives in a record you already resolved, and most integrations ignore it.
Use it as a ranking signal rather than a hard filter. Filtering on it alone collapses your pool to people actively looking, who are also the people every other recruiter is contacting. The better use is to surface it in the UI so a recruiter can prioritise within a shortlist they already trust.
Lookalike expansion
The motion that makes a sourcing product feel intelligent, and the one most products skip.
A recruiter has someone who fits. Maybe a previous placement, maybe a current employee at the client, maybe one strong result from an earlier search. Rather than asking them to articulate a filter expression, start from the person.
1eid = renidly.live.people.resolve_handle("jane-doe")   # resolve once, cache it
2similar = renidly.live.people.lookalikes(eid)1const eid = await renidly.live.people.resolveHandle("jane-doe");
2const similar = await renidly.live.people.lookalikes(eid);This is better than criteria search for a specific reason: a recruiter can recognise a good fit far more easily than they can describe one. "More people like her" is a question they can answer instantly, and the filter expression that would produce the same set is something they would struggle to write.
Build it as a button on every candidate record. It is one call and it changes how the product feels.
Resolve the handle to a stable identifier once and reuse it. Handles can change; identifiers do not, which is covered in the profile lookup API guide.
Alumni sourcing
Underused, and strong for two very different briefs.
1alumni = renidly.data.institutions.alumni(
2    "stanford",
3    degree="master",
4    field_of_study="computer science",
5    end_year_min=2018,
6    end_year_max=2022,
7    geo_country_code="US",
8    sort="recently_graduated",
9)1const alumni = await renidly.data.institutions.alumni("stanford", {
2 degree: "master",
3 field_of_study: "computer science",
4 end_year_min: 2018,
5 end_year_max: 2022,
6 geo_country_code: "US",
7 sort: "recently_graduated",
8});The normalized_name is lowercase and hyphenated, and you discover it through institution search. Year ranges let you target a graduating cohort precisely, which matters for graduate programmes and for "five to eight years post-qualification" briefs.
Each result is a professional record plus the education record that links the person to the institution, so you can show a recruiter why someone surfaced.
The second use is company alumni rather than school alumni, and it is the one recruiters care about most. For that, the employees endpoint has a parameter worth knowing:
1leavers = renidly.data.companies.employees(
2    slug="northwind-logistics",
3    current_only=False,
4    sort="recently_left",
5    limit=50,
6)
sort="recently_left" with current_only=False returns people who recently departed a company. For a recruiter that is a high-intent pool: they have already made the decision to leave, they are in market, and they carry domain knowledge from a named competitor.
Supporting this well means letting a user name a company and get its recent leavers, which is a feature most sourcing products do not have.
Trigger sourcing
The same logic at the level of events rather than companies.
1moves = renidly.data.job_changes.search(
2    event_type="left",
3    organization_ids="org_5ehe8408s7tme,org_06d0d44dogo2m",
4    days_ago=30,
5    title="engineer",
6    limit=50,
7)1const moves = await renidly.data.jobChanges.search({
2 event_type: "left",
3 organization_ids: "org_5ehe8408s7tme,org_06d0d44dogo2m",
4 days_ago: 30,
5 title: "engineer",
6 limit: 50,
7});Three event types exist: joined, left and title_change. For recruiting, left is the valuable one and almost nobody monitors it systematically.
Two implementation details that break first versions:
This endpoint takes organization identifiers (org_…), while people search takes organization slugs. They are not interchangeable.
The endpoint returns a recency window, not a changelog. Running it daily with a thirty-day window returns the same people every day. You need a seen-set keyed on a stable identifier with a TTL longer than your widest window, or your users will be shown the same candidates repeatedly. The full pattern is in job change signals.
From a match to a contactable person
A search result is a record. A recruiter needs someone they can actually reach, and that is three separate questions.
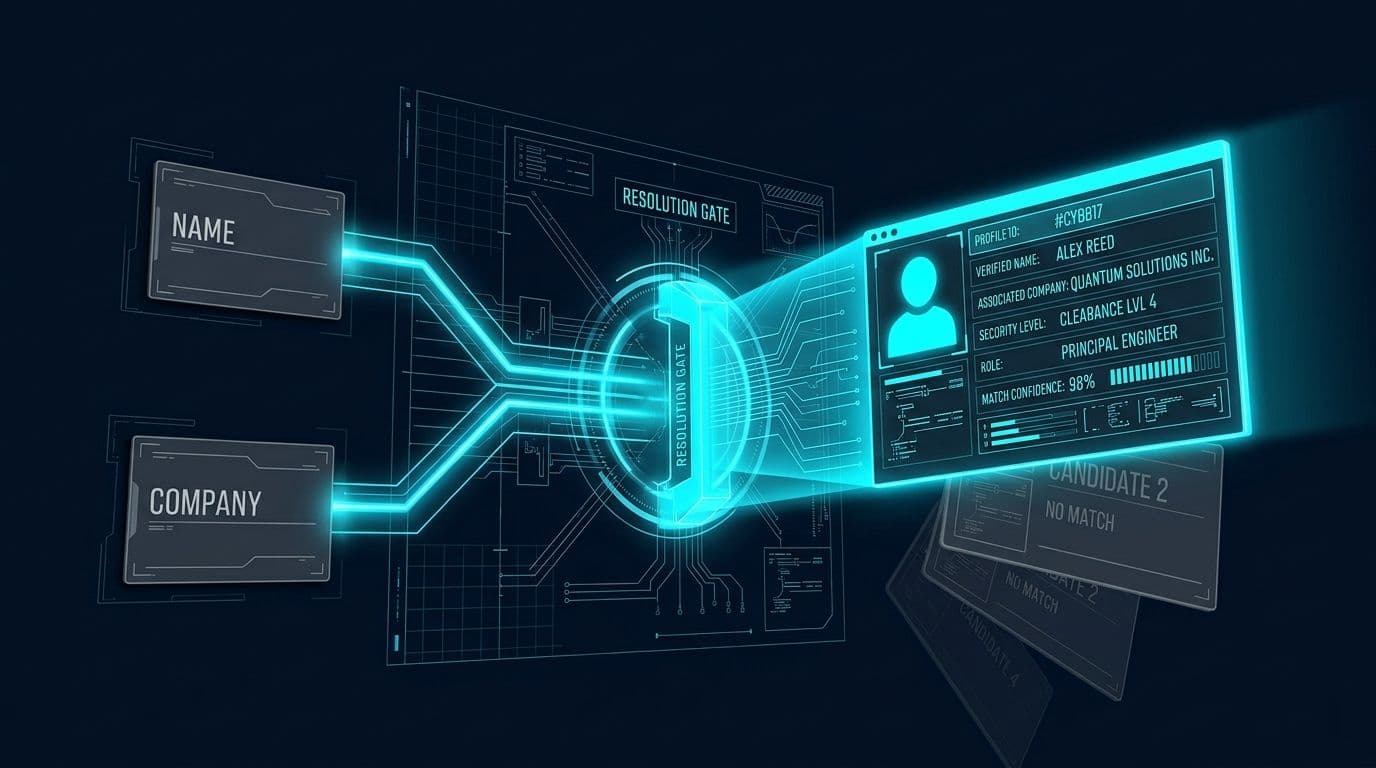
Who is this? The profile record: name, current role, employer, history, skills, education.
Where do they work now? This is not the same question. A record can be correct about a person and out of date about their employer, because every provider has detection lag. For anything a recruiter is about to act on, confirm the current role.
How do I reach them? A work email, found and verified.
1found = renidly.emails.find(
2    first_name="Jane",
3    last_name="Doe",
4    domain="northwind-logistics.com",   # bare hostname, no scheme, no @
5)
6
7if found.found and found.confidence == "high":
8    check = renidly.emails.verify(found.email)
9    if check.deliverable and not check.catch_all:
10 surface_to_recruiter(found.email)1const found = await renidly.emails.find({
2 firstName: "Jane",
3 lastName: "Doe",
4 domain: "northwind-logistics.com",
5});
6
7if (found.found && found.confidence === "high") {
8 const check = await renidly.emails.verify(found.email);
9 if (check.deliverable && !check.catchAll) {
10 await surfaceToRecruiter(found.email);
11 }
12}Two things specific to recruiting.
Catch-all domains are everywhere in this market. Large employers, universities, hospitals and public sector organisations disproportionately run mail servers that accept every address, which means verification cannot confirm the specific mailbox. If you source into those sectors, a meaningful share of your addresses will come back unconfirmable. Treat them as their own segment rather than as clean, and the full handling is in catch-all email domains.
A verified address can belong to someone who left. Mailboxes at large employers often stay open and forwarding for months. Verification plus employment confirmation is the pair that works; neither alone is sufficient. That distinction is the core of verified candidate data.
If you hold a profile URL rather than a name and company, there is a direct path that resolves the current employer for you before searching:
1found = renidly.emails.find_by_url("https://example.com/in/jane-doe")Keeping a talent pool current
Recruiting databases decay faster than almost any other kind, for a structural reason: your records are about candidates, and a candidate is by definition someone who changes jobs.
Worse, the successful outcome of your own process invalidates your own data. The moment you place someone, their employer, title and work email all change.
Three practices that work:
Refresh by field, not on a schedule. Position history is append-only and never changes. Education never changes. Current title, employer and work email die on a job change. Refreshing everything annually over-refreshes the permanent fields and under-refreshes the volatile ones.
Watch for movement rather than re-resolving. Re-enriching asks what is true now. Watching events asks whether anything happened, and the second is far cheaper because job changes drive most of the decay. Instead of refreshing fifty thousand records to find the four thousand that changed, watch for the four thousand events.
Refresh on access, not only on schedule. When a recruiter opens a candidate record they have not touched in six months, that is the moment to resolve fresh. It is one call, the user is already waiting, and it prevents the worst outcome, which is a recruiter contacting someone about a role at a company they left.
The field-level decay model is in CRM data decay, and it applies directly to talent pools.
Building it into a product
Four architectural decisions that matter once real users are on it.
Search latency is user-facing
A recruiter typing a brief expects results in a second or two. That shapes everything.
Use dataset reads for search, not live resolution. Dataset reads are fast and consistent, which is what a search box needs. Live resolution returns the freshest available state for one subject and is the right call when a recruiter opens a specific candidate, not when they are scanning a list.
Paginate rather than pulling everything. Search is cursor-paginated with up to fifty per page. Load the first page, let the user scroll.
Cache aggressively on your side. The same brief run twice in an afternoon should not cost twice.
Store identifiers, not names
Every resolved person carries a stable opaque identifier like prsn_06d0d44dogo2m, and every organization one like org_5ehe8408s7tme. These never change.
1person = renidly.data.people.retrieve(handle="jane-doe")
2
3if person:
4    store_candidate_id(record_id, person.id)    # prsn_…, not the handle
The failure mode if you store the handle instead is specific and silent. The person edits their profile, your next refresh returns a not-found, and if your code treats not-found as "no data" it writes null over a populated candidate record. Nothing errors.
Worth knowing: a lookup that resolves nothing returns HTTP 200 with a flag in the body rather than 404, because the request succeeded and the answer is empty. Branch on the response body, not the HTTP status. The reasoning is in what B2B identity resolution actually is.
Hydrate in bulk, not in loops
When a user imports a list or you backfill a client's existing pool, use batch rather than per-record calls:
1job = renidly.data.people.enrich_batch(ids=[c.person_id for c in cohort])
2
3for row in job.stream():
4 upsert(row.matched_input, row)1const job = await renidly.data.people.enrichBatch({ ids: cohort.map(c => c.personId) });
2
3for await (const row of job.stream()) {
4 await upsert(row.matched_input, row);
5}Up to a thousand per job, results keyed back to exactly what you submitted, streaming so a crash partway through does not discard completed work. The full pattern including completion tracking is in bulk profile lookup.
Leave rate limit headroom
If one key serves both your interactive search and your background hydration, a large import will starve the search box.
1from renidly import Renidly, RenidlyConfig
2
3renidly = Renidly(config=RenidlyConfig(
4    auto_rate_limit=True,
5    rate_limit_safety=0.7,     # bulk work capped, interactive path protected
6    max_retries=3,
7))
Better still, use separate keys for interactive and bulk work, which per-request overrides make straightforward.
What it costs
The arithmetic that determines your margin if you resell this inside a product.
1cost            = records submitted × rate
2usable records  = records submitted × resolution rate
3effective cost  = cost ÷ usable records
Lookups that resolve nothing are billed, because producing a definitive no-match takes the same work as producing a record. At a 60% resolution rate, effective cost per usable record is roughly 1.7 times the headline rate.
Two things specific to a recruiting product:
Measure your resolution rate by segment, not overall. Senior and technical roles resolve considerably better than frontline, shift-based and trade roles. If your product serves hospitality or logistics recruiting, your blended rate will look poor and the cause is your market rather than the provider. Knowing it by segment lets you set expectations with customers instead of apologising.
Search pages are billed individually. A user who scrolls through ten pages of results costs ten requests. Either cap what a single search returns or price your product with that in mind.
Every response carries the credits it consumed:
1print(page.meta.credit_consumed, page.meta.remaining_balance)Measure your own rate on a five-hundred-record sample before pricing anything. Current per-route costs are on the pricing page.
Compliance, specifically for recruiting
Recruiting carries obligations that general B2B prospecting does not, because the decisions affect whether someone gets considered for work.
Keep a human in the loop on anything that filters people out. Automated decisions with significant effects on individuals carry specific legal obligations in several jurisdictions, and recruiting is the canonical example. Scoring and ranking to help a recruiter prioritise is one thing; automatically rejecting is another.
Audit what your ranking actually weights. Names, institutions, languages and locations can proxy for protected characteristics. A model that learns those correlations does so whether or not anyone intended it. If you rank candidates automatically, check what the model is actually using.
Honour opt-outs permanently. When a provider signals that someone has withdrawn from resolution, that is durable, not transient. Build the suppression list on first occurrence and check it before every lookup, not only after.
Retain deliberately. Candidate records legitimately persist longer than sales leads, because someone who was not right in 2023 may fit in 2026. That is a defensible purpose if you have stated it. "We never delete anything" is not.
Let candidates correct their own record. If your product shows someone data about themselves, give them a path to fix it, and make corrections survive the next refresh.
The fuller treatment is in responsible profile lookup, and the use case shape is on the recruiting and HR page.
Eight mistakes
Leaving skills_match on its default. You are running a union and thinking you are running an intersection.
Omitting current_only. Your results include people who held the role a decade ago.
Building only criteria search. Lookalike expansion is one call and changes how the product feels.
Treating is_open_to_work as a filter rather than a ranking signal. It collapses the pool to the people every other recruiter is already contacting.
Storing handles as foreign keys. They change, and the failure is silent.
Skipping employment confirmation. A verified address belonging to someone who left is the most embarrassing possible outcome for a recruiter.
Polling an event window as if it were a changelog. Your users see the same candidates every day.
Pricing without measuring resolution rate by segment. Your margin on a hospitality client is not your margin on a software client.
Frequently asked questions
What is a candidate sourcing API?
An API that returns professional records matching structured criteria such as role, skills, education, location and career stage, so a recruiting product can find candidates who are not already in its own database.
How is it different from a candidate enrichment API?
Sourcing starts from criteria and returns many people. Enrichment starts from a candidate you already have and fills in missing fields. Most recruiting products need both.
What filters should it support?
Beyond title and location: current-role scoping, normalized skills with all-match logic, education and institution filters, tenure bands, recent career movement, and availability flags. The last three are where a usable shortlist comes from.
Can I find people who recently left a specific company?
Yes, two ways. The employees endpoint sorted by recent departures, or the job-change event stream filtered to left for named organizations.
How do I find more people like a candidate I already have?
Lookalike expansion from that person's stable identifier. It is usually better than criteria search, because recognising a fit is easier than describing one.
How accurate is candidate data?
Expect a resolution rate between 50% and 75% on a realistic list, varying heavily by seniority and sector. Senior and technical roles resolve better than frontline ones. Measure your own by segment.
Do I pay for searches that return nothing?
Yes, because producing a definitive no-match takes the same work. Budget on records submitted rather than returned, and remember each page of results is billed separately.
Can automated sourcing decisions reject candidates?
Keep a human in the loop for anything that filters people out. Automated decisions with significant effects on individuals carry specific obligations in several jurisdictions.
The one-line version
Criteria search is table stakes and it is not enough. The motions that make a sourcing product feel built by someone who has recruited are lookalike expansion from one good example, alumni sourcing by school and by former employer, and trigger sourcing on people who just left somewhere.
Set skills_match to all and current_only to true, or your results will be wider than your users expect in ways they will blame on you. Use tenure bands rather than seniority labels, because two to five years in a role predicts movability better than a title does.
Store the stable identifier rather than the handle. Confirm current employment separately from verifying the email address, because a deliverable address belonging to someone who left is the worst outcome a recruiter can hand a client.
And measure resolution rate by segment rather than overall, because your margin on one vertical is not your margin on another, and finding that out from a customer is worse than finding it out from a sample.
If you want to test the resolution rate on your own candidate pool before building anything, there are 100 free credits with no card required. The Quickstart takes about five minutes, the free tools will resolve a single candidate with no signup, and for volume pricing or a procurement conversation, talk to us directly.