Getting a profile lookup to work is easy. Getting it to still be right in a year is the actual problem.
Most teams start the same way: someone writes a script, resolves a few thousand records, and the results look good. Eighteen months later the same database is full of stale titles, duplicate people, records nobody can explain, and a sales team that has quietly gone back to manual research because they stopped trusting what they were being shown.
Nothing dramatic went wrong. The failures were all small, cumulative and silent.
This covers the practices that prevent that: what to do before you look anything up, how to decide what to trust, how to store it, when to refresh, and how to know whether any of it is working. It is written for whoever owns the result rather than for whoever writes the first script.
What "good" actually looks like
A useful standard, because without one you cannot tell whether you are succeeding.
A profile lookup practice is working when:
- Every stored field can answer three questions: where it came from, at what confidence, and when it was last verified.
- Nothing automated has ever destroyed something a human entered.
- You can state your resolution rate and your effective cost per usable record from your own logs, without asking anyone.
- The people consuming the data trust it, which you measure by whether they still do their own research alongside it.
- A record going stale produces a signal, rather than being discovered by someone being embarrassed on a call.
Most teams fail the first and the last. Those two are where the discipline lives.
Before you look anything up
Define the question you are answering
The most common waste in this whole category is resolving records nobody will ever look at.
Most databases contain a long tail that will never be queried: leads from a 2019 trade show, accounts outside your current ICP, contacts at companies you no longer sell to. Resolving them costs money and produces nothing, and the cost is invisible because it arrives as one undifferentiated invoice.
Decide before you start:
Which records matter. Open pipeline, active accounts, current ICP, anything a human will actually touch this quarter.
Which fields matter. Not all forty. Pick the five to ten that actually drive routing, scoring or outreach. Every additional field is more surface area for errors nobody is checking.
What accuracy you need. Territory assignment tolerates a wrong headcount band. Personalized outreach does not tolerate a wrong employer. Those are different standards and pretending they are one standard means you over-engineer one and under-serve the other.
If you cannot name who will act on a field, do not resolve that field.
Clean your inputs first
Input quality determines outcome quality more than any provider difference, and most volume jobs fail here rather than at the API.
Split names properly. A single full_name column needs splitting, and splitting on the first space breaks compound surnames and particles. Where you have structured first and last name fields, use them.
Normalize domains to bare hostnames. Company fields in the wild contain full URLs, email addresses, company names and occasionally phone numbers. A resolution call expecting acme.com will reject https://www.acme.com/about.
Deduplicate before submitting. The same person appearing three times is three billed lookups for one record. Deduplicate on the strongest key you have, usually email, before anything reaches the API.
Drop rows that cannot possibly resolve. No domain, no name, a domain with no dot. Filter them rather than paying to be told they are invalid.
1def prepare(rows: list[dict]) -> list[dict]:
2    seen, out = set(), []
3
4    for r in rows:
5        email = (r.get("email") or "").strip().lower()
6        domain = extract_hostname(r.get("company") or "")
7
8        if not email and not (r.get("first") and r.get("last") and domain):
9            continue                       # cannot resolve, do not submit
10
11        key = email or f"{r['first']}|{r['last']}|{domain}".lower()
12        if key in seen:
13            continue                       # dedupe before spending
14        seen.add(key)
15
16        out.append({**r, "domain": domain})
17
18    return out
Running this before a 50,000-record job routinely removes 15 to 30% of the submissions. That is a direct cost saving before you have called anything.
Choosing the right resolution path
Different inputs have different reliability, and using the strongest one available is free accuracy.
| You hold | Use | Why |
|---|---|---|
| A stable identifier | Direct retrieve by ID | Exact, no matching |
| A work email | Reverse resolution | Near-unique, graded confidence |
| A profile URL or handle | Resolve, then store the ID | Exact for that profile |
| Name + company domain | Find by name and domain | Good, but names collide |
| Name only | Filtered search, not lookup | Not a unique key |
The practice: resolve once from whatever you hold, store the stable identifier, and use the identifier for everything afterwards.
1from renidly import Renidly
2
3renidly = Renidly()  # reads RENIDLY_API_KEY from the environment
4
5person = renidly.data.people.retrieve(handle="jane-doe")
6
7if person:
8    store_person_id(record_id, person.id)      # persist prsn_…, not the handle
If your stack is Node, the same discipline:
1import { Renidly } from "renidly";
2
3const renidly = new Renidly();
4
5const person = await renidly.data.people.retrieve({ handle: "jane-doe" });
6
7if (person) {
8  await storePersonId(recordId, person.id);
9}
The reason this matters is covered in depth in the profile lookup API guide, and the short version is that handles change, identifiers do not, and a pipeline keyed on something changeable fails silently rather than loudly.
Match the freshness to the job
Two modes exist and using one for everything is a mistake in both directions.
A dataset read is fast, consistent and cheap, and it is correct for bulk work where small staleness is acceptable. A live resolution returns the freshest available state for one subject, and it is correct when a human is waiting or the answer feeds a decision that is expensive to get wrong.
The practice that works: split the run. Dataset reads for the long tail, live resolution for the accounts that matter.
1# Bulk hydration: dataset read
2for row in renidly.data.people.search(
3    organization_slugs="northwind-logistics",
4    current_only=True,
5).auto_paging_iter():
6    upsert(row)
7
8# Target account, rep is about to call: resolve fresh
9snapshot = renidly.live.people.enrich(handle="jane-doe")
Paying live rates across a hundred thousand cold records is waste. Using a dataset read for the twenty accounts your team is actively working is false economy.
Confidence discipline
This is the single practice that separates a database people trust from one they do not.
Never treat a match as binary
A graded confidence value exists so you can behave differently depending on certainty. Collapsing it to "we got something" throws away the only quality signal you have.
| Confidence | Action |
|---|---|
high | Write directly |
medium | Write, flag for periodic review |
low | Stage for human review, do not write to the live record |
none | Do not write, and do not overwrite anything existing |
1def route(result) -> str:
2    if not result.found or result.confidence == "none":
3        return "no_write"
4    if result.confidence == "high":
5        return "write"
6    if result.confidence == "medium":
7        return "write_flagged"
8    return "review_queue"
Require two attributes, not one
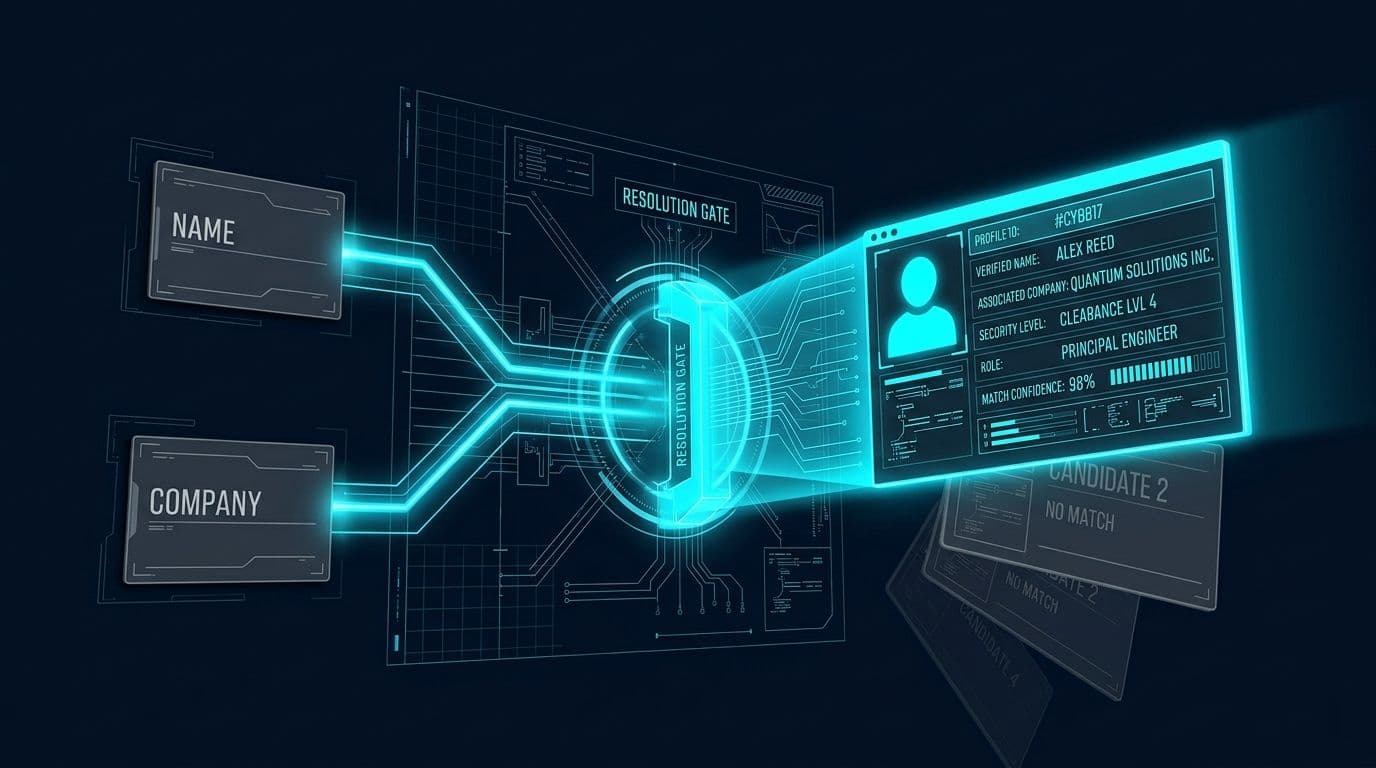
A single matching attribute is a candidate. Two independent ones is an identification.
Name plus company is one attribute for this purpose, because both came from the same source record and neither independently confirms the other. Add role, location, tenure, or a previous employer, ideally from a source other than the one that gave you the name.
This matters most exactly where errors are most expensive: common names, large companies, and anyone who recently moved.
Verify the thing you are about to act on
Resolution and verification answer different questions, and conflating them produces confident failures.
A person can be correctly resolved and have a dead email address. An address can be deliverable and belong to someone who left four months ago. If you are about to send something, check both, and the mechanics are in the email verification API guide.
Storage practices
The API calls are the easy part. How you store the result decides whether the system is still useful later.
Provenance on every field
Three pieces of metadata alongside each enriched value: source, confidence, verified_at.
Without them you cannot prioritize a refresh, cannot audit a decision, and cannot tell the people using the data which fields to trust. Most databases do not give you this for free, so it usually means companion columns or a parallel table. It is unglamorous plumbing and everything else in this post depends on it.
Keep enriched values separate from human ones
An enriched_title column alongside title lets you compare, audit and roll back. Writing enrichment straight into the field a human edits means you can never tell what came from where, and the first time someone disputes a value you will have no way to answer them.
Keep the raw response
Store the full payload alongside the parsed fields. Schemas evolve, you will eventually want a field you did not originally parse, and reprocessing stored responses is free while re-fetching is not.
Write rules that cannot be bypassed
Put these in one function that every write path goes through. If each integration implements its own rules, one of them will get it wrong.
1def should_write(field, current, incoming, confidence) -> bool:
2    if not incoming:                  return False   # never overwrite with nothing
3    if field in HUMAN_OWNED_FIELDS:   return False   # notes, owner, stage
4    if human_edited(field):           return confidence == "high"
5    if not current:                   return confidence in ("high", "medium")
6    if current == incoming:           return False   # no-op, do not churn the audit log
7 return confidence == "high" # replacing good data needs certainty1function shouldWrite(
2 field: string,
3 current: string | null,
4 incoming: string | null,
5 confidence: "high" | "medium" | "low" | "none",
6): boolean {
7 if (!incoming) return false;
8 if (HUMAN_OWNED_FIELDS.has(field)) return false;
9 if (humanEdited(field)) return confidence === "high";
10 if (!current) return confidence === "high" || confidence === "medium";
11 if (current === incoming) return false;
12 return confidence === "high";
13}The asymmetry is deliberate. Filling an empty field is low risk. Replacing a value someone may already have acted on requires certainty.
The rule that prevents the worst incident: an empty result must never overwrite a populated field. This gets violated constantly by bulk jobs that treat null as a value, and it is the single most destructive bug in enrichment because it removes information rather than adding wrong information.
Refresh practices
Refresh by field, not by calendar
The most common refresh strategy is "re-run everything quarterly," and it is wrong in both directions at once: it over-refreshes stable fields and under-refreshes volatile ones.
| Field | Volatility | Refresh |
|---|---|---|
| Current title | High, changes on promotion and job change | Before outreach, short cycle |
| Current employer | High, dies on a job change | Before outreach, short cycle |
| Work email | High, tied to employment | Before outreach |
| Location | Moderate | Long cycle |
| Skills, certifications | Low, mostly additive | Annually |
| Education | None | Never |
| Position history | None, append-only | Never |
Position history is the one people miss. Past roles do not change. Once resolved, that portion of a record is permanently correct, which means re-pulling full records to refresh a title is paying for data you already have and that cannot have changed.
Prioritize rather than refreshing everything
Score each record and refresh within a budget:
1priority = decay_likelihood × business_value × stalenessWhere decay likelihood comes from the field table above, business value is whatever your organization already uses, and staleness is time since verified_at.
Refresh descending until the budget runs out. In practice this means refreshing 10 to 20% of a database per cycle and capturing most of the value, because decay concentrates in a minority of records.
Score on the worst field rather than the average. A record whose email is probably dead needs attention even if everything else is stable, because the dead email is what breaks the workflow.
Detect change instead of re-resolving
The highest-leverage practice in this entire post, and the one most teams never build.
Re-enriching asks "what is true now?" Watching for movement asks "did anything happen?" The second is far cheaper, because job changes drive most of the decay in professional data.
Instead of refreshing 50,000 records to find the 4,000 that changed, watch for the 4,000 events:
1moves = renidly.data.job_changes.search(
2    event_type="joined",
3    organization_ids="org_5ehe8408s7tme,org_06d0d44dogo2m",
4    days_ago=7,
5    limit=50,
6)1const moves = await renidly.data.jobChanges.search({
2 event_type: "joined",
3 organization_ids: "org_5ehe8408s7tme,org_06d0d44dogo2m",
4 days_ago: 7,
5 limit: 50,
6});Three event types exist: joined, left and title_change. The implementation detail that breaks every first version is deduplication, because the endpoint returns a recency window rather than a changelog, so a daily poll with a 30-day window returns the same people every day. Keep a seen-set with a TTL longer than your widest window. Full pattern in job change signals.
Note the parameter difference that catches people out: this endpoint takes organization IDs, while people search takes organization slugs. They are not interchangeable.
The broader field-level decay model is in CRM data decay.
Cost practices
Budget on submissions, not results
The arithmetic that surprises teams:
1cost            = records submitted × rate
2usable records  = records submitted × resolution rate
3effective cost  = cost ÷ usable records
Lookups that resolve nothing are billed, because producing a definitive no-match takes the same work as producing a record. At a 60% resolution rate, effective cost per usable record is roughly 1.7 times the headline rate.
Measure your own resolution rate before sizing anything. It is specific to your data, and a 500-record sample takes ten minutes:
1probe = renidly.data.people.enrich_batch(ids=sample_500).wait()
2rate = probe.resolved / probe.total
3print(f"resolution rate: {rate:.1%}")
Re-measure before each large run rather than once. Rates drift as your input mix changes.
Put a ceiling in the runner
1BUDGET, spent = 50_000, 0
2
3for idx, chunk in enumerate(chunks):
4    if spent >= BUDGET:
5        log.warning("budget ceiling reached at chunk %s", idx)
6        break
7    result = renidly.data.people.enrich_batch(ids=chunk).wait()
8    spent += result.meta.credit_consumed
Six lines. A runaway loop is the standard way a routine backfill becomes an uncomfortable conversation with finance.
Read cost per call rather than reconstructing it
Every response carries the credits it consumed, outside the response data so there is no field collision:
1print(p.meta.credit_consumed, p.meta.remaining_balance)1console.log(p.meta.creditConsumed, p.meta.remainingBalance);Emit both to your metrics pipeline from the first call. Cost per usable record is the number you will be asked for, and reconstructing it from invoices later is miserable. Per-route costs are published at a public endpoint needing no key, and current rates are on the pricing page.
Use batch, always, for lists
Submitting up to 1000 items in one request is not just faster. It avoids generating a thousand requests to be rate limited, gives you resumability, and keys results back to your exact inputs.
1for row in renidly.data.people.enrich_batch(ids=chunk).stream():
2 upsert(row.matched_input, row)1const job = await renidly.data.people.enrichBatch({ ids: chunk });
2for await (const row of job.stream()) await upsert(row.matched_input, row);Stream rather than wait when writing to a database, so a failure partway through does not discard completed work. Track completion per chunk so a restart does not redo finished work, because resubmitting a chunk you already completed doubles its cost for zero additional data. The full pattern is in batch enrichment at scale.
Operational practices
Leave rate limit headroom
1from renidly import Renidly, RenidlyConfig
2
3renidly = Renidly(config=RenidlyConfig(
4    auto_rate_limit=True,
5    rate_limit_safety=0.7,     # bulk work capped at 70% of the ceiling
6    max_retries=3,
7))
A client-side limiter holding you under the ceiling is far better than discovering it through rejections. The safety factor is what stops a backfill from starving whatever interactive path shares the key. Running bulk work at 100% of your limit alongside a live signup flow is a self-inflicted outage.
Handle each error class differently
| Error | Retry? | Action |
|---|---|---|
| Invalid request | No | Fix the input, log the field |
| Permission denied (opted out) | Never | Permanent suppression list |
| Insufficient credits | No | Alert operations, pause the run |
| Rate limited | Yes | Back off, or enable auto limiting |
| Service unavailable | Yes | Backoff |
| Connection error | Yes, then fall back | Backoff |
The one that costs money quietly: opt-outs are permanent, not transient. If they fall into a generic retry path, every batch run you ever execute re-requests the same records forever for a guaranteed nothing. Build the suppression list on first occurrence and check it before submitting.
Make workers idempotent
Queues retry. Without a claim pattern you get duplicate writes and doubled cost tracking.
1def enrich_once(record_id: str, identifier: str) -> None:
2    key = f"enrich:{record_id}:{identifier}"
3    if not claim(key, ttl_hours=24):
4        return
5    try:
6        person = renidly.data.people.retrieve(id=identifier)
7    except (ServiceUnavailableError, APIConnectionError):
8        release(key)                 # transient: allow retry
9        raise
10    except PermissionDeniedError:
11        mark_excluded(record_id)     # permanent: hold the claim
12        return
13    write_fields(record_id, person)
14    mark_complete(key)
Release the claim on transient failures. Hold it on permanent ones, because they will not succeed on a second attempt.
Never return enriched data to the browser
If a user-facing endpoint returns the resolved record to the client, anyone can submit arbitrary identifiers to your form and read the data back. You have built a free public lookup API and you are paying for it.
The client receives a decision, not a record. If the UI genuinely needs to display something, return that one field and nothing else.
Measuring whether it is working
Four numbers. If you are not tracking these, you cannot know, and an unmeasured pipeline drifts into being expensive without anyone noticing.
| Metric | What it tells you |
|---|---|
| Resolution rate, by segment | Coverage gaps in a market or company-size band |
| Write rate vs attempt rate | Whether your governance rules are firing as expected |
| Fields changed per refresh | Whether refresh is finding anything or churning |
| Cost per corrected field | Whether your prioritization is working |
The last one is the honest measure. If you refresh 10,000 records and 400 fields change, you paid for 10,000 lookups to fix 400 things. Watch that ratio over time: if it degrades, your prioritization is sending you at records that were not going to change, and the fix is in the scoring rather than the budget.
Two alerts worth having from day one. A balance floor, because a backfill draining the pool your production path depends on is an incident. And a resolution-rate drop, because a sharp week-over-week fall means something changed upstream and you want that from a dashboard rather than from a colleague complaining.
Measure the thing that actually matters
Beyond the operational metrics, there is one quality measure that tells you whether this work has value: does the team using the data still do their own research alongside it?
If reps are checking every record manually before acting, the enrichment is not trusted, and no amount of coverage improvement fixes a trust problem. Trust is lost through confident wrong answers, which is why the confidence discipline earlier in this post matters more than raw match rate.
A maturity model
Useful for working out where you are and what to fix next, rather than trying to do everything at once.
Level 1: Ad hoc
Someone resolves records manually or with a throwaway script. No storage discipline, no provenance, no refresh. Fine for a pilot, dangerous the moment anyone starts depending on the output.
Next step: store a stable identifier on every resolved record. Nothing else matters until that exists.
Level 2: Scripted
A repeatable script exists. Records are resolved in bulk, results are written somewhere. Still no provenance, no confidence routing, and refresh is manual.
Next step: add provenance columns and a single write-gate function that every path goes through.
Level 3: Pipeline
Batch jobs, idempotent workers, error handling by class, rate limit headroom. Results land reliably.
Next step: add confidence-based routing and protect human-entered values.
Level 4: Governed
Field-level write rules, provenance per field, human edits protected, a documented mapping of which source owns which field.
Next step: replace calendar refresh with priority-scored refresh and change detection.
Level 5: Monitored
Resolution rate tracked by segment, cost per corrected field tracked over time, alerts on balance and quality drift, and refresh driven by movement events rather than a schedule.
At level 5 the system tells you when it is degrading, which is the whole point.
Most teams sit at level 2 and believe they are at level 4. The test is simple: pick a field on a record and ask where it came from, at what confidence, and when it was last checked. If nobody can answer, you are at level 2.
Twelve anti-patterns
Keying on handles or names. They change. The failure is silent.
Branching on HTTP status instead of the response body. A not-found returns 200, so a status-only check treats it as success and writes nulls.
Letting empty overwrite populated. The most destructive bug available, because it removes information rather than adding wrong information.
Treating every match as equal. Confidence exists so you can route, not so you can log it.
One matching attribute. Name plus company from the same source record is one attribute, not two.
Resolving records nobody will query. Pure cost, invisible in a single invoice.
Refreshing everything on one cycle. Over-refreshes stable fields, under-refreshes volatile ones.
Re-resolving instead of detecting change. Pays full price to confirm that most records did not change.
Retrying opt-outs. Permanent condition, infinite retries, guaranteed zero return.
Looping single calls over a list. Rate-limited, slow, no resumability.
Budgeting on results rather than submissions. Misses are billed and your maths will be off by the inverse of your resolution rate.
Returning enriched records to the browser. You have built someone else's free API.
Frequently asked questions
What is the most important practice in profile lookup?
Storing a stable opaque identifier on first resolution and refreshing against that rather than against a name or handle. Everything else is recoverable; a database keyed on changeable strings breaks silently and expensively.
How often should profile data be refreshed?
By field rather than on a schedule. Current title and employer change on a job change, so refresh before acting. Position history and education never change and never need refreshing.
What is a good resolution rate?
Between 50% and 75% on a realistic B2B list, varying heavily by geography, seniority and industry. Measure your own on a 500-record sample rather than relying on any published figure.
Should I resolve my entire database?
Usually not. Most databases contain a long tail nobody will ever query, and resolving it is cost with no return. Prioritize by business value and staleness, refresh within a budget, and let the tail go.
How do I stop enrichment from damaging my data?
One write-gate function that every path goes through, enforcing that nothing empty overwrites something populated, nothing uncertain overwrites something confident, and nothing automated overwrites something a human entered.
Do I pay for lookups that return nothing?
Yes. Producing a definitive no-match takes the same work as producing a record, which is why a miss returns 200 rather than 404. Budget on records submitted.
What should I monitor?
Resolution rate by segment, write rate against attempt rate, fields changed per refresh, and cost per corrected field. The last is the honest measure of whether your prioritization works.
How do I know if the data is trusted?
Watch whether the people consuming it still do their own research alongside it. If they do, you have a trust problem, and trust is lost through confident wrong answers rather than through missing records.
The one-line version
Decide what you are resolving and why before you resolve anything, because most waste in this category is spent on records nobody will ever look at.
Clean your inputs, because input quality determines outcome more than any provider difference. Store the stable identifier, not the name. Put provenance on every field: source, confidence, and when it was checked. Route on confidence rather than treating every match as equal, and require two independent attributes before you call something an identification.
Refresh by field rather than by calendar, since position history never changes and current employer dies the day someone leaves. Where you can, detect change rather than re-resolving, because that turns a database-wide refresh into a short queue of records you already know are wrong.
And put every write through one gate that cannot be bypassed. Nothing empty overwrites something populated, nothing uncertain overwrites something confident, nothing automated overwrites a human. A database with gaps is recoverable. A database people have stopped believing is not.
If you want to measure your own resolution rate before building any of this, there are 100 free credits with no card required, which covers a 500-record sample comfortably. The Quickstart takes about five minutes, the free tools will resolve a single record with no signup, and for volume or a procurement conversation, talk to us directly.